A neural network is a computer model that learns to recognize patterns by adjusting a large set of small numbers, loosely inspired by how brain cells pass signals to one another. Instead of following hand-written rules, it studies many examples, such as photos labeled “cat” or “not cat,” and tunes itself until its guesses are mostly right.
It sits behind face unlock on your phone, voice typing, spam filters, and the chatbots now common in American offices and classrooms. This guide covers how a neural network is built, how it learns, the main types, and where it still fails. A few small calculations are included so the idea feels concrete.
Why It Is Called a Neural Network
The name comes from biology. A brain cell receives signals, and if the combined input is strong enough, it fires and passes a message on. A 2009 study led by Frederico Azevedo and Suzana Herculano-Houzel in the Journal of Comparative Neurology put the human brain at about 86 billion neurons.
Artificial neural networks borrow that basic idea, and the resemblance ends quickly. Artificial neurons are simple math functions with no chemistry, no fatigue, and no ability to rewire themselves over years. The brain was an inspiration, and the design is far simpler, so picturing a tiny digital brain leads to wrong expectations.
Neural Network vs AI vs Machine Learning
These terms nest like dolls. Artificial intelligence is the broad goal of machines doing tasks that need human-like judgment. Machine learning is one approach, where systems learn from data. A neural network is one kind of machine learning model, alongside others such as decision trees and linear regression.
Neural networks are not always the best choice. On small spreadsheet-style datasets, simpler models like gradient-boosted trees often match or beat them and are easier to explain.
How a Neural Network Is Built
1. Neurons, Weights, and Bias
Each artificial neuron takes in numbers, multiplies each by a weight, adds the results, and then adds a bias. A weight says how much an input matters. A bias shifts the total up or down, like a default lean before any evidence arrives.
Take a neuron that decides whether to carry an umbrella. Its inputs are cloud cover (0.8 on a scale from 0 to 1) and the forecast chance of rain (0.9). With weights of 0.5 and 1.0 and a bias of -0.6, the sum is 0.8 x 0.5 + 0.9 x 1.0 – 0.6, which equals 0.7.
That 0.7 then goes through an activation function. A sigmoid function turns it into about 0.67, which you can read as a 67 percent lean toward taking the umbrella.
2. Layers
One neuron can only reach simple conclusions, so a network stacks many into layers. The input layer receives raw data, such as the pixel values of a photo. Hidden layers sit in the middle, and the output layer gives the answer, such as “cat” at 94 percent confidence.
Early hidden layers tend to pick up edges and color patches. Later ones combine those into shapes and then whole objects. A network with many hidden layers is called a deep neural network, which is where the term deep learning comes from.
3. Activation Functions
Without activation functions, stacked layers would collapse into one plain calculation, because a chain of multiplications and additions is still just multiplications and additions. The activation adds the bend that lets a network model curved, messy patterns. The most common choice today is ReLU, which outputs zero for negative numbers and passes positive numbers through unchanged.
How a Neural Network Learns
1. Guess, Measure, Adjust
Training starts with random weights, so early guesses are poor. The network predicts, and a loss function measures how far off it was. If it rained in the umbrella example, the right answer was 1, so a prediction of 0.67 leaves an error of 0.33.
Weights that pushed the answer the wrong way get nudged down, and weights that helped get nudged up. Repeat this across thousands or millions of examples and the error shrinks.
2. Backpropagation and Gradient Descen
Backpropagation is the method for working out which weights to nudge. It traces the error backward from the output through each layer and calculates how much each weight contributed. David Rumelhart, Geoffrey Hinton, and Ronald Williams popularized it in a 1986 paper in Nature.
Gradient descent takes the actual steps. Picture standing on a foggy hillside, feeling the slope underfoot, and stepping downhill. The step size is the learning rate: too large and training overshoots, too small and it crawls.
3. Overfitting and How Teams Catch It
A network can memorize its training data instead of learning general patterns. You see it when accuracy is excellent on training examples and poor on new ones. Teams catch this by holding back a separate test set, and they reduce it with early stopping or dropout, which randomly switches off neurons during training.
Main Types of Neural Networks
1. Feedforward Networks
This is the simplest design. Data moves in one direction, from input to output. These networks suit structured data such as loan application fields or sales figures.
2. Convolutional Neural Networks
CNNs slide small filters across an image, so they spot features wherever they appear in the frame. Yann LeCun and colleagues used this approach in the 1990s to read handwritten digits, and their 1998 paper described a system for reading bank checks. Modern CNNs power photo tagging and many medical imaging tools.
3. Recurrent Neural Networks
RNNs carry a memory of earlier inputs, which suited them to speech and text. They struggle with long passages, and the LSTM design introduced by Sepp Hochreiter and Jürgen Schmidhuber in 1997 eased that problem.
4. Transformers
The 2017 Google paper “Attention Is All You Need” by Ashish Vaswani and colleagues introduced transformers, which let a model weigh every word in a passage against every other word at once. They are the architecture behind large language models such as the GPT family. The 2020 GPT-3 paper by Tom Brown and colleagues reported 175 billion parameters, where a parameter is one adjustable weight or bias.
A Short History of Neural Networks
Warren McCulloch and Walter Pitts described a mathematical neuron in 1943. Frank Rosenblatt demonstrated the perceptron in 1958 with funding from the U.S. Office of Naval Research. Marvin Minsky and Seymour Papert’s 1969 book Perceptrons then exposed limits of single-layer designs, and funding cooled for years.
Backpropagation revived interest in the 1980s. The turning point came in 2012, when AlexNet, built by Alex Krizhevsky, Ilya Sutskever, and Hinton, won the ImageNet contest with a top-5 error of 15.3 percent against 26.2 percent for the runner-up. In 2024, Hinton and John Hopfield shared the Nobel Prize in Physics for foundational work on artificial neural networks.
Where Americans Already Use Neural Networks
Most people meet a neural network daily without noticing. Face unlock, voice assistants, photo search, and autocorrect all rely on them. Waymo’s driverless rides in cities such as Phoenix and San Francisco use them to interpret camera and sensor data.
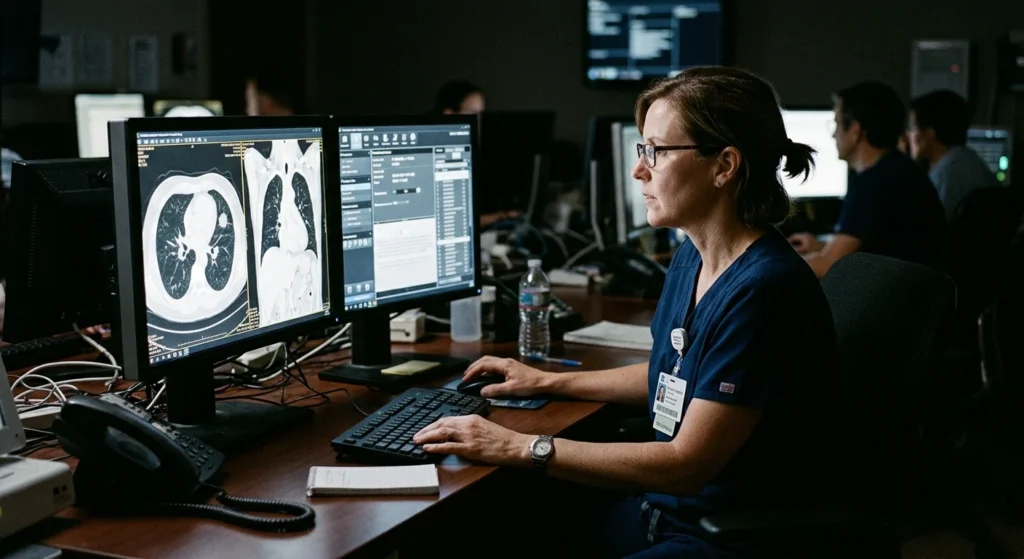
In medicine, the FDA keeps a public list of AI-enabled medical devices, and radiology makes up most of it. The U.S. Postal Service has long used machine reading of handwriting to sort mail. Banks use neural networks to flag unusual card activity, which is why a purchase in another state can trigger a text asking if it was you.
Limits and Risks Worth Knowing
Neural networks need a lot of data and computing power, and their mistakes can be hard to explain. A trained network is a pile of numbers, not a set of readable rules, so even its builders may not know why it flagged one loan or missed one tumor.
Bias is a documented problem. In the 2018 Gender Shades study, Joy Buolamwini and Timnit Gebru found that commercial face-analysis systems had error rates up to 34.7 percent for darker-skinned women, compared with 0.8 percent for lighter-skinned men. The cause was largely unbalanced training data.
A network is also only reliable on data that resembles what it saw in training. Show it something unusual and it can answer confidently and wrongly.
How to Start Learning Neural Networks Hands-On
The fastest way to build intuition is to watch one train. The TensorFlow Playground at playground.tensorflow.org lets you add layers and neurons in a browser and watch the decision boundary change. The 3Blue1Brown video series on neural networks explains the math visually.
When you want to code, Python with PyTorch or TensorFlow is the standard route. Andrew Ng’s Machine Learning Specialization on Coursera and the free fast.ai course are well-known starting points. Begin with a small project, like classifying handwritten digits from the MNIST dataset.